


GRC Audit Management That Actually Works

A surprising number of audit programmes fail because they're designed to prepare for audits rather than maintain control between them. In the UAE, regulated entities already operate under a formal accountability chain: the Central Bank rulebook requires a Board-approved Risk Governance Framework based on the three lines of defense, an independent internal audit function, documented internal controls, periodic review, and reporting of findings to the audit committee. Central Bank of the UAE requirements make clear that assurance is a governance obligation, not an annual administrative exercise.
GRC audit management should therefore be treated as continuous evidence engineering. Your controls need owners, your obligations need mappings, your systems need evidence connections, and your findings need remediation workflows that remain visible to management until closure.
Why Annual Audits Fail GCC Enterprises
Annual audits leave long periods without reliable assurance. During those gaps, configurations change, access rights accumulate, vendors evolve, policies become outdated, and evidence disappears into email threads. By the time testing begins, the audited environment may no longer resemble the environment that produced the original records.
The UAE's regulatory direction reinforces the need for stronger evidence discipline. The Ministry of Economy reported 24 meetings, 23 violation cases reviewed, and 20 disciplinary decisions in one year for the accounting and auditing professions, according to its professional compliance and governance update. The activity reflects scrutiny of evidence quality, professional oversight, and timely accountability.
The board should ask a sharper question: can management identify control drift before an external reviewer finds it?
The annual-cycle failure pattern
A conventional audit programme usually follows a predictable sequence:
Scope late: Teams define the audit perimeter after business changes have already occurred.
Request manually: Control owners search for screenshots, approvals, logs, tickets, and policy records.
Test briefly: Auditors review a sample that may not represent current operating conditions.
Report slowly: Findings reach leadership after the underlying control environment has changed.
Close administratively: Teams mark actions complete without proving that the root cause has been removed.
This process rewards document production over dependable control operation. It also hides the cost of stale evidence until an auditor challenges the result.
UAE public companies provide a structured example of the shift toward ongoing control accountability. In January 2024, the Securities and Commodities Authority introduced corporate governance amendments for listed public joint-stock companies. Stage One in FY 2024 required internal control self-assessment and external auditor review. Stage Two in FY 2025 required a full audit of the internal control over financial reporting framework and public disclosure of deficiencies and remediation actions, as explained in PwC's analysis of the SCA amendments.
Board-level test: If the dashboard shows only completed tasks, it measures activity. A useful dashboard shows current exposure, evidence freshness, overdue remediation, and confidence in critical controls.
Continuous evidence engineering changes the operating model. Access reviews, vulnerability information, incident records, configuration changes, policy attestations, and remediation tickets become reusable evidence streams. Their board-level value is measurable: earlier visibility into exposure, clearer ownership of remediation, and stronger confidence that critical controls still operate.
Internal audit, external audit, compliance, and regulatory reviewers can then work from a controlled evidence trail instead of repeatedly requesting the same files. For a practical discussion of how weak narratives undermine GRC credibility, see DataLunix's perspective on GRC anecdotes.
Make audit readiness a property of normal operations, not a project launched shortly before fieldwork.
What GRC Audit Management Means
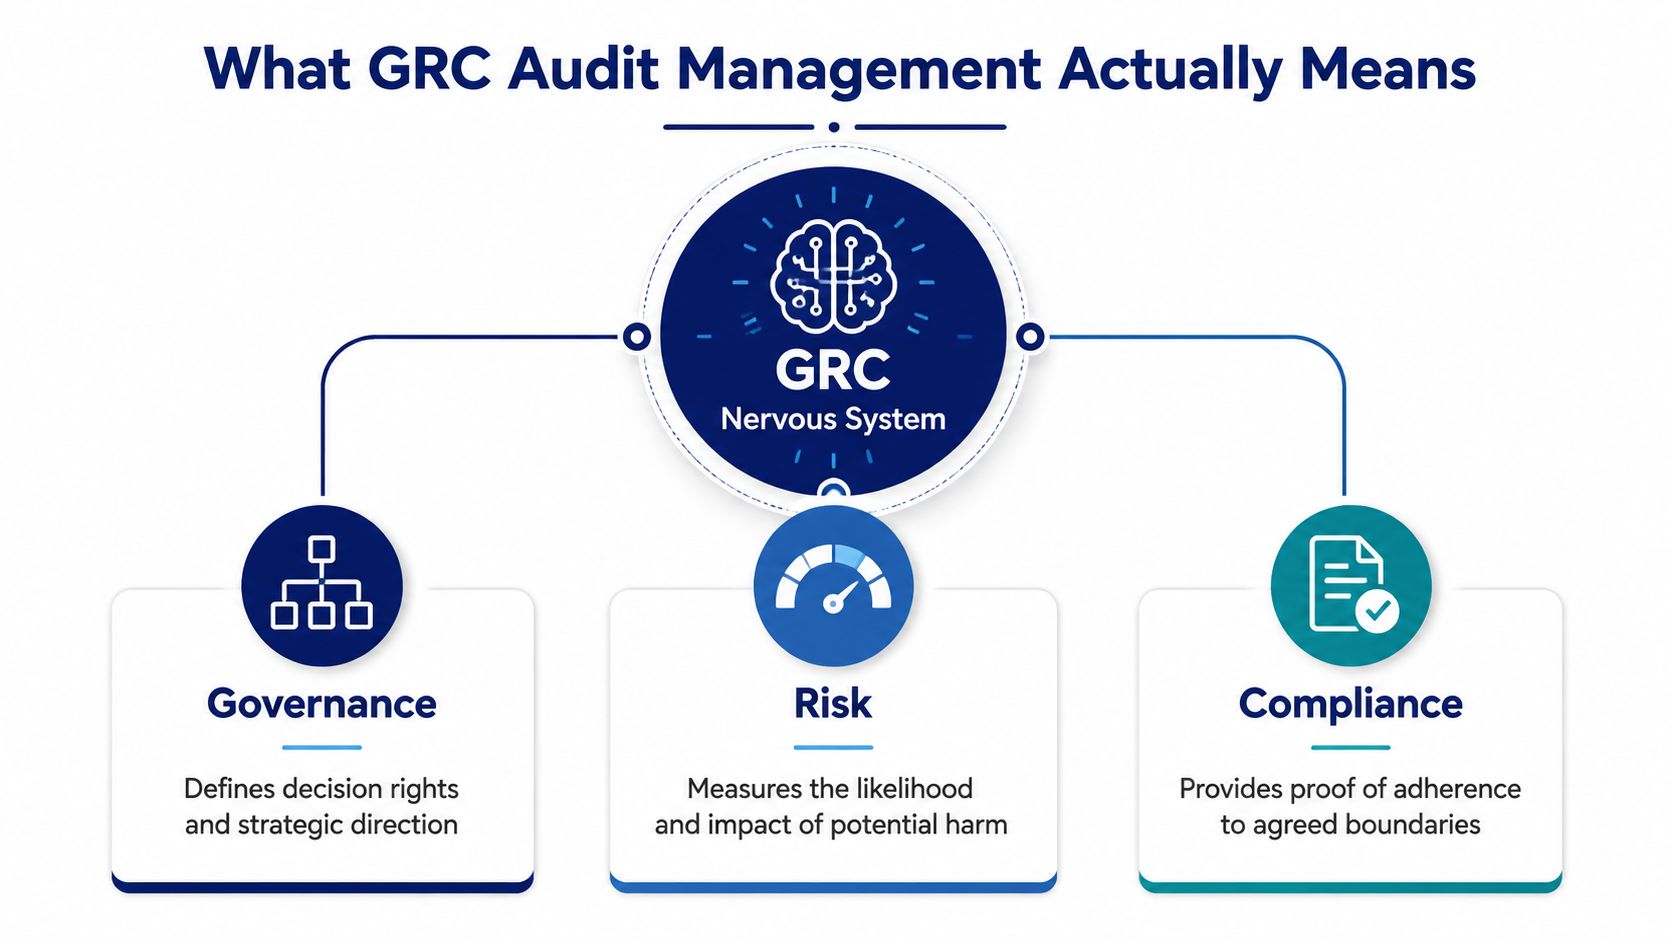
GRC audit management is a continuous evidence-engineering discipline. It connects assurance planning, obligations, controls, evidence, testing, findings, and remediation in one operating model. The objective is practical: give executives a current view of control performance, residual exposure, remediation ownership, and confidence in reported results.
Annual checklists fail because they capture activity at a point in time. A useful audit-management system links each control to its policy, obligation, risk, process, system, owner, test procedure, evidence, incident history, and remediation record. That connection lets audit teams test whether controls are designed and operating as claimed, while giving the board clearer answers about exposure and accountability.
The three operating pillars
A workable model has three connected capabilities:
Unified control library: Maintain one authoritative catalogue for policies, regulatory obligations, risks, processes, systems, owners, test procedures, and evidence requirements. Use control inheritance so a single control can support several frameworks without disconnected spreadsheet copies.
Automated evidence collection: Pull relevant proof from identity platforms, ITSM tools, SIEM systems, HR records, cloud services, and business applications. Automation removes repetitive searching and preserves evidence metadata, while reviewers retain responsibility for assessing relevance and quality.
Actionable remediation workflows: Convert findings into assigned actions with an owner, due date, risk context, validation criteria, and escalation path. Closing a ticket does not prove that the underlying risk has been reduced.
Internal audit provides the independent assurance layer. UAE guidance describes it as an independent and objective activity that examines whether governance, risk management, and internal controls operate as claimed, rather than merely confirming that policies exist. Monitoring observes operations. Audit validates design, operation, evidence, and follow-up.
The operating principle is simple: make audit readiness a property of normal work. Access reviews, vulnerability information, incident records, configuration changes, policy attestations, and remediation tickets should produce reusable evidence streams. For a broader explanation of how governance, risk, and compliance connect, see DataLunix's GRC overview. Mature programmes reduce repeated evidence requests and give the board faster, better-grounded answers.
Core Frameworks and How to Mix Them
Framework selection is engineering, not religion. A mid-to-large GCC enterprise rarely needs one framework in isolation. It needs a control backbone, governance ownership, risk language, and jurisdiction-specific overlays.
Framework | Primary focus | GCC applicability | Overlap potential | Best fit for |
|---|---|---|---|---|
ISO 27001 | Information security management | Strong cross-industry relevance | High with NIST and regulatory controls | Organisations building an auditable security management system |
ISO 31000 | Enterprise risk management | Useful as a risk-management layer | High with governance and risk registers | Enterprises standardising risk identification and treatment |
COBIT 2019 | IT governance and management | Useful for technology accountability | High with ISO and IT control families | CIO-led governance and decision-rights models |
SOC 2 | Service-organisation trust criteria | Relevant to service providers and technology firms | Moderate with ISO security controls | Organisations proving trust practices to customers |
NIST CSF 2.0 | Cybersecurity risk management | Practical cyber-resilience backbone | High with ISO and national controls | Security teams needing outcome-oriented cyber governance |
NESA or SAMA controls | Local regulatory and sector obligations | Directly relevant where mandated | High with security and resilience controls | UAE or Saudi entities subject to specific regulatory requirements |
For most larger GCC organisations, I'd start with ISO 27001 plus NIST CSF as the control backbone. Add COBIT 2019 when technology governance, accountability, and management practices need clearer ownership. Layer ISO 31000 across enterprise risk registers, and apply NESA, SAMA, DESC, Central Bank, or other jurisdictional requirements where they govern the entity.
The mapping principle is more important than the brand of framework. One internal control should satisfy multiple clauses where the intent overlaps. If identity recertification is copied separately for ISO, NIST, SAMA, and an internal standard, the organisation will test the same activity four times and still struggle to explain ownership.
The UAE Information Assurance Standard illustrates why generic checklists fail. The framework spans 12 domains, includes 208 controls, and contains 250 total mappings, with audit and accountability requirements covering auditable events, storage capacity, monitoring and reporting, record retention, and timestamps. Regional guidance on the UAE cybersecurity audit landscape shows why evidence architecture must extend beyond IT into ownership, retention, logging, exceptions, and compensating controls.
Track ISO 42001 as an emerging AI governance layer, but don't add it as another isolated checklist. Map AI governance obligations to existing risk, security, privacy, model, procurement, and change-management controls.
For a wider framework comparison, review DataLunix's guide to GRC frameworks across the EU, US, UK, and GCC.
The Audit Lifecycle From Planning to Remediation
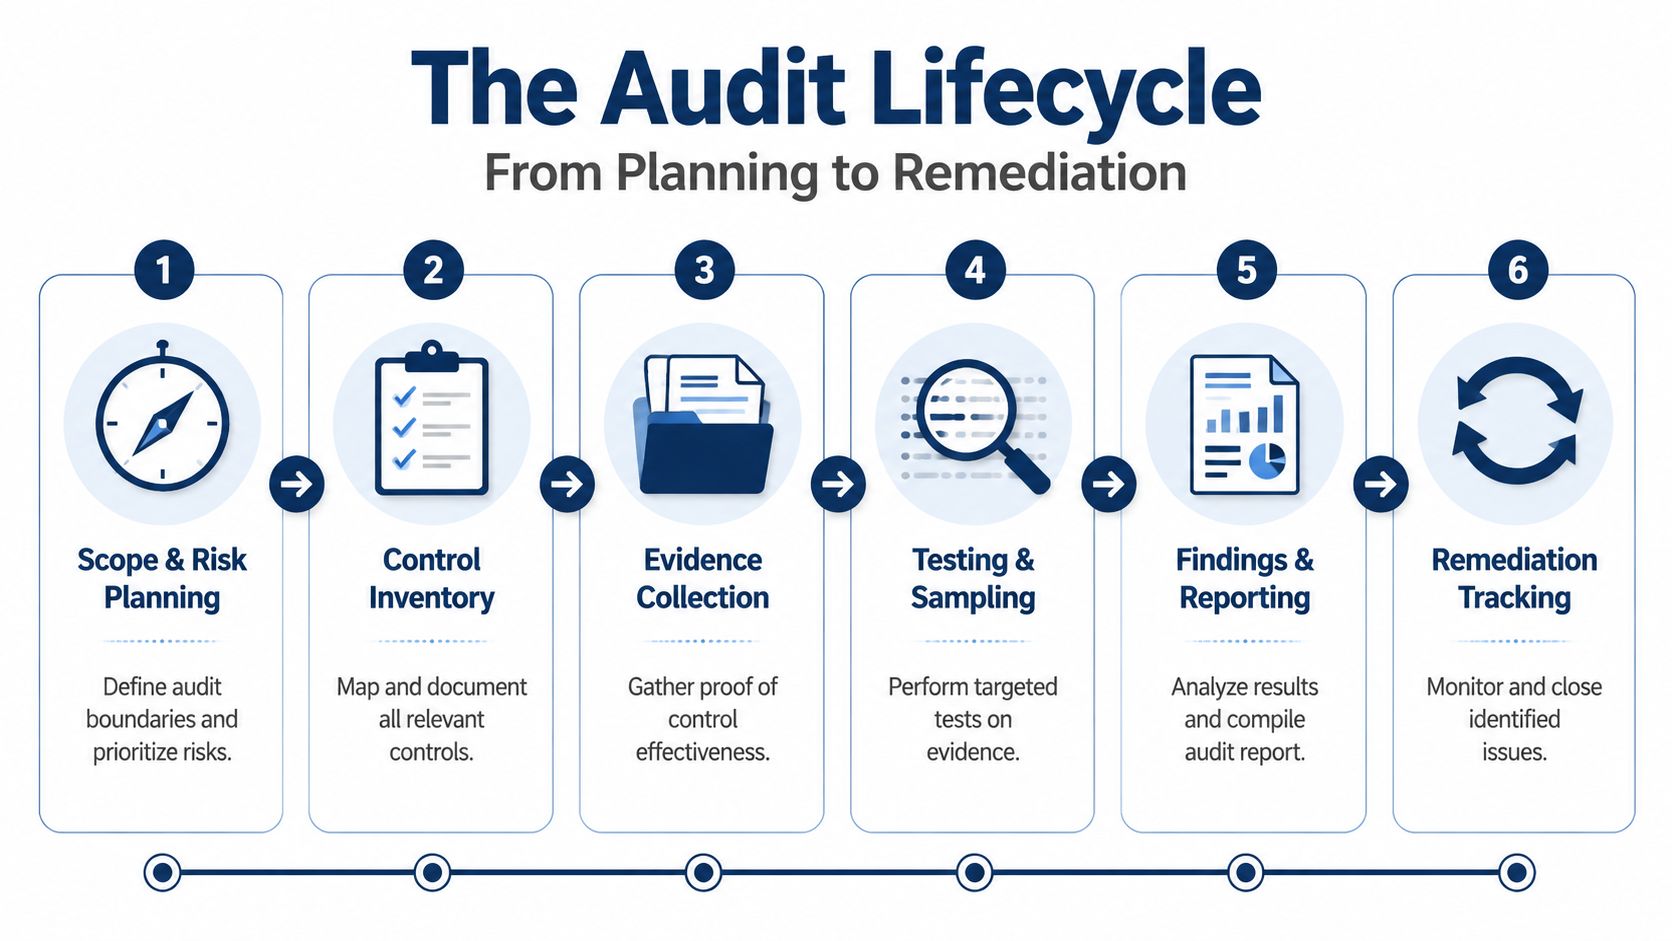
A mature audit lifecycle is a repeatable chain of decisions and evidence. It's not a decorative process diagram. Each phase needs a named owner and an artefact that another reviewer can inspect.
Six phases that hold up under scrutiny
Scope and risk planning: The audit lead defines boundaries, objectives, jurisdictions, systems, business units, and risk priorities. The risk champion supplies the relevant risk register entry, including changes that could alter audit focus.
Control inventory: The control owner and audit lead establish the control catalogue and risk-control matrix. The core artefact is an RCM row that identifies control intent, frequency, owner, systems, evidence, test method, and linked obligations.
Evidence collection: The control owner provides proof through integrations or controlled uploads. A system screenshot, approval record, configuration export, access review, log extract, or ticket can be useful, but only when its date, source, scope, and integrity are clear.
Testing and sampling: The control tester examines design and operating effectiveness. A sample log should show the population, selection method, test steps, exceptions, reviewer, and conclusion. Continuous evidence can reduce repetitive requests, but it doesn't remove the need for professional judgement.
Findings and reporting: The audit lead documents the finding memo, including condition, criteria, cause, impact, risk rating, owner, and recommendation. The CISO or accountable executive should understand the business consequence, not just the technical defect.
Remediation tracking: The remediation PM manages the CAPA ticket, while the original control owner completes the action and the tester validates closure. Closure needs evidence that the risk was addressed, not merely a status change to “done”.
What to measure
Don't judge the lifecycle by the number of controls ticked. Judge it by:
Time to evidence: How quickly can an authorised reviewer obtain complete, traceable proof?
Testing quality: Can the tester explain why the sample supports the conclusion?
Closure velocity: Are owners resolving root causes or repeatedly requesting extensions?
Evidence reuse: Can the same trustworthy artefact support multiple assurance activities?
Board visibility: Can executives see material exposure without interpreting five unrelated spreadsheets?
The GRC process guidance from DataLunix is useful as a practical reference point. The sequence works across frameworks because it separates planning, control definition, proof, testing, reporting, and remediation instead of blending them into one vague “audit workflow”.
Tooling and ITSM Integration Considerations
A GRC platform without operational context becomes shelf-ware. An ITSM platform without a risk and control layer creates noise. Your architecture needs both the control view and the service view.
The audit team should own the control catalogue, test methodology, evidence requirements, and assurance calendar. IT should own service records, configuration items, incidents, changes, requests, and operational tasks. Reconciliation jobs must keep those records aligned.
Four integration patterns worth implementing
CMDB synchronisation: Connect business services, applications, infrastructure, vendors, and configuration items to the controls and risks they support. Bidirectional synchronisation helps prevent stale ownership and scope records.
Evidence webhooks from ticketing: Pull approved change records, incident histories, problem-management actions, and service requests into the relevant control evidence set.
IAM attestations: Trigger access reviews, segregation-of-duties checks, privileged-access monitoring, and joiner-mover-leaver evidence from identity systems rather than asking managers to complete disconnected forms.
SIEM risk signals: Stream relevant security findings, incidents, and control exceptions into risk scoring and audit prioritisation. The audit team still interprets significance, but it shouldn't wait for a quarterly report to discover a pattern.
Platform | Best fit profile | Key strength | Watch out for |
|---|---|---|---|
ServiceNow GRC or IRM | Complex enterprises with broad service-management estates | Deep workflow, CMDB, risk, audit, and enterprise-service integration | Requires disciplined data ownership and implementation governance |
HaloITSM | Organisations seeking flexible ITSM with a pragmatic operating model | Configurable service workflows and operational records | GRC depth may require careful design and complementary tooling |
Freshservice | Mid-market teams prioritising rapid service-management adoption | Accessible ITSM workflows and broad integration options | Complex regulatory mapping may need additional governance architecture |
ManageEngine ServicePlus | Organisations already invested in the ManageEngine ecosystem | Practical service, asset, and operations alignment | Control taxonomy and assurance reporting need deliberate configuration |
DataLunix's ServiceNow GRC perspective provides context for connecting audit workflows with the wider ServiceNow environment. DataLunix can also support integrations across ServiceNow, HaloITSM, Freshservice, and ManageEngine, while keeping the control catalogue separate from the operational systems that generate evidence.
A 90-Day Implementation Roadmap
A 90-day launch should build an operating model, not just install software. The first month is decisive because it establishes ownership, scope discipline, framework choices, and evidence standards before stakeholders become tired of another transformation programme.
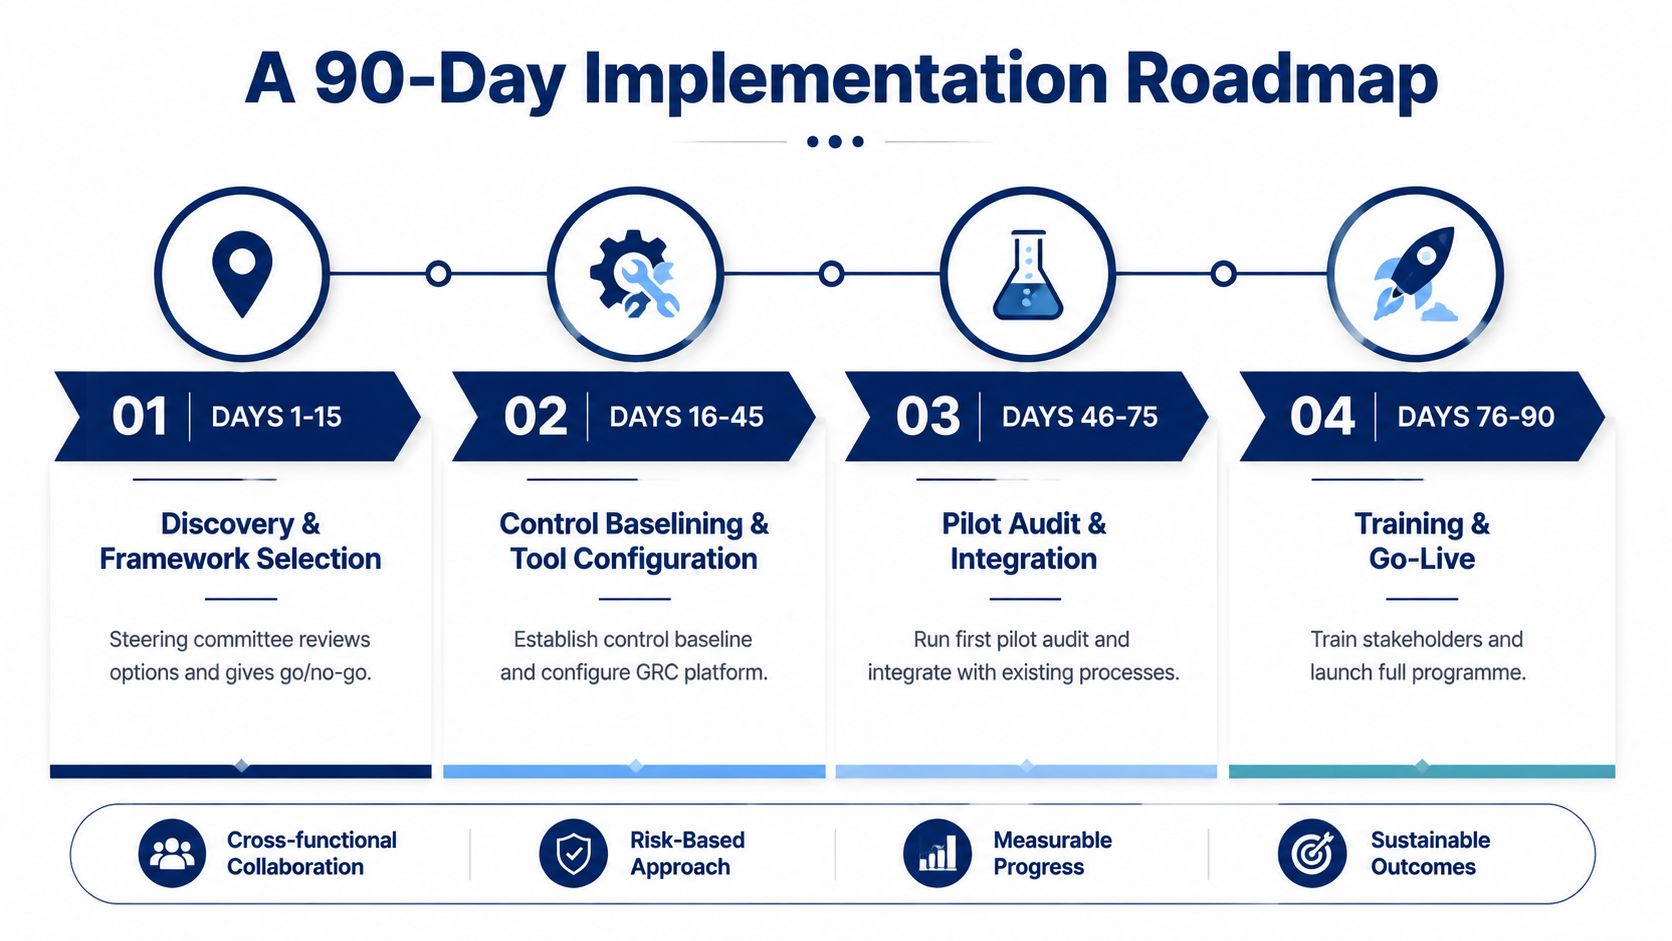
Sprint one, days 1 to 15
Run discovery workshops with the CIO, CISO, risk, compliance, internal audit, IT operations, data protection, procurement, and key business owners. Select the initial framework mix, identify the highest-value audit scope, document current evidence sources, and agree the minimum viable control taxonomy.
Decision gate: The steering committee gives a go or no-go decision on scope, ownership, priority obligations, and the first evidence sources. If these aren't agreed, don't configure the platform yet.
Sprint two, days 16 to 45
Baseline the controls, configure roles and workflows, create the risk-control matrix, define test procedures, and connect selected ITSM, IAM, SIEM, HR, and document repositories. Finish with a controlled pilot scope rather than attempting enterprise-wide coverage.
Decision gate: Pilot sign-off confirms that owners understand their responsibilities, evidence can be retrieved, findings can be assigned, and remediation can be validated.
Sprint three, days 46 to 75
Roll out to two business units with different risk profiles. Run a pilot audit, reconcile control records against service data, test escalation paths, and measure evidence quality. Keep the capability assessment focused on whether teams can operate the model without constant consulting support.
Decision gate: Scale only when the pilot demonstrates usable ownership, reliable evidence, workable testing, and visible remediation accountability.
Sprint four, days 76 to 90
Train stakeholders, publish operating procedures, establish the audit calendar, define executive reporting, and prepare the managed-service handover. Baseline the agreed KPIs and document which activities remain with internal teams versus the implementation partner.
Decision gate: Go-live requires named owners, approved workflows, escalation routes, a support model, and a review date for the first operating cycle.
Common Pitfalls and How to Fix Them
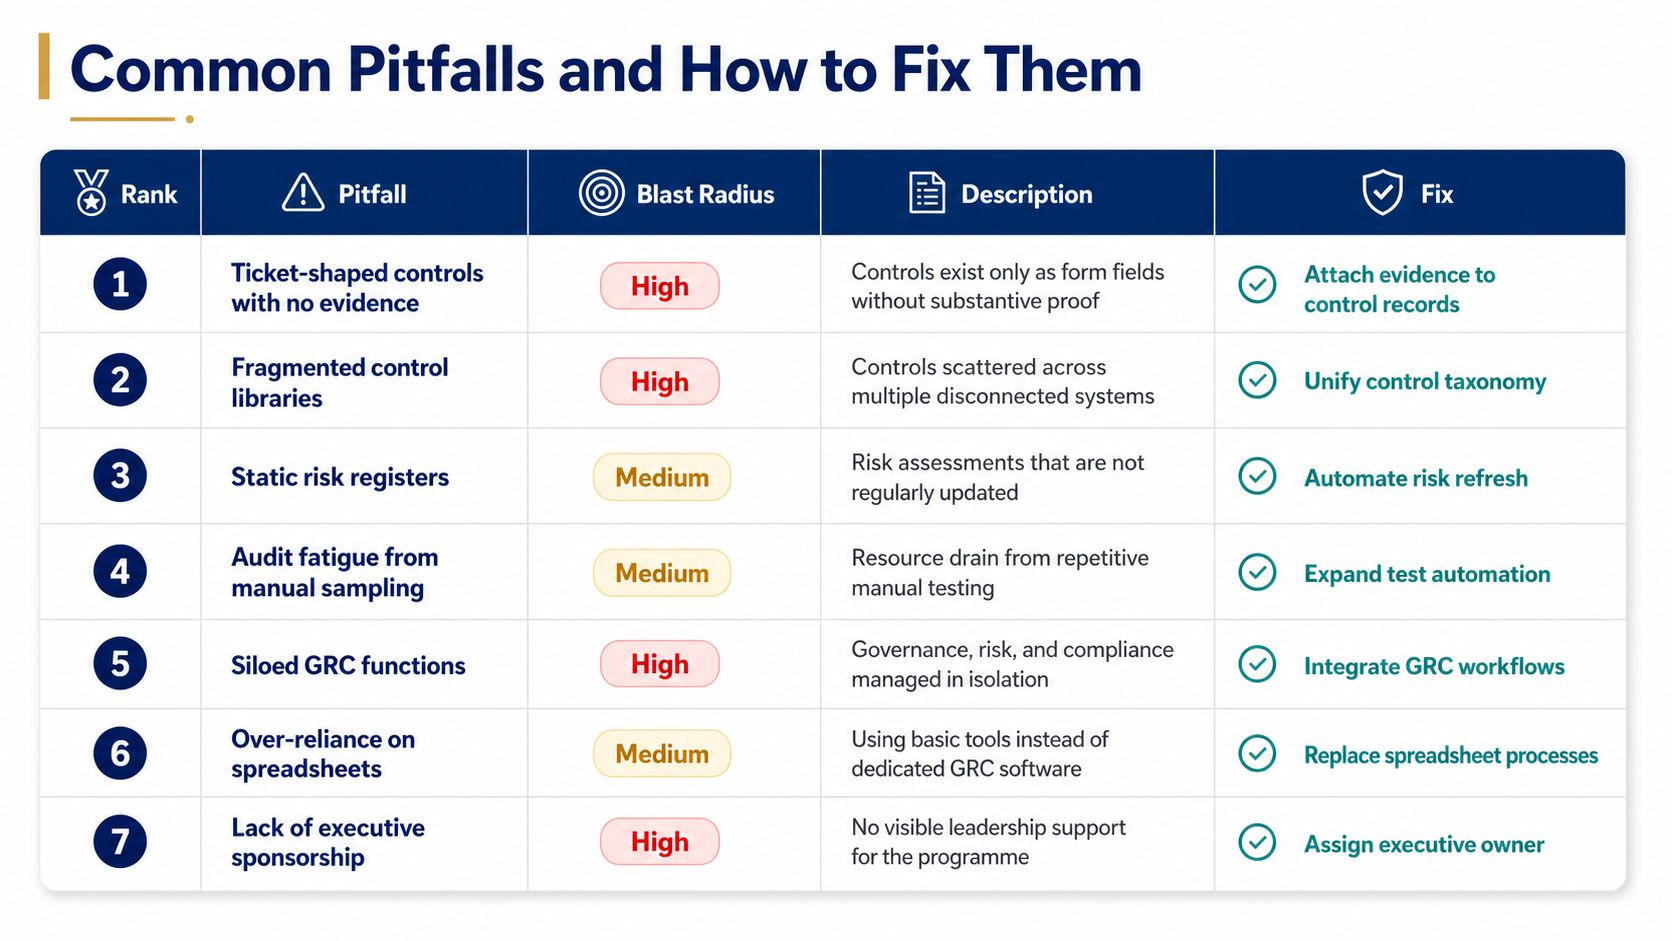
The biggest failures aren't caused by a lack of policy documents. They're caused by weak connections between controls, evidence, people, and operational systems.
The seven antipatterns I'd challenge first
Ticket-shaped controls with no evidence, high blast radius: A form field says “review completed” but contains no substantive proof. Use evidence-as-code or automated evidence capture, with source, timestamp, scope, and reviewer metadata.
Fragmented control libraries, high blast radius: ISO, NESA, SAMA, internal policies, and customer commitments live in separate repositories. Build one canonical control library with inheritance and framework mappings.
Spreadsheet-driven evidence collection, medium blast radius: Email requests and local folders create version confusion. Route evidence through controlled workflows and connect it to the underlying system record.
Weak issue-to-remediation traceability, high blast radius: Findings sit apart from incidents, changes, problems, and CAPA actions. Link remediation to the event or process failure that created the finding.
Compliance theatre, high blast radius: Teams optimise for polished audit packs instead of control performance. Give the board operational KPIs, recurring-finding analysis, and unresolved risk exposure.
Ignoring recurring assurance cycles, medium blast radius: Annual VAPT, annual risk assessment, ISO internal audit, surveillance activity, and technical checks are managed as separate reminders. Automate frequencies and maintain one audit calendar.
Ownership ambiguity, high blast radius: Risk, IT, compliance, and internal audit each assume another team owns the control. Document the three-lines-of-defence RACI and make accountability visible in every workflow.
The Central Bank's required separation of governance, internal control, and independent internal audit supports this ownership discipline. The programme should mirror that accountability rather than creating a single compliance team responsible for every control in the business.
Next Steps and a Practical Checklist
Score your programme against these verification questions today:
Governance: Has the board approved the risk and control accountability model?
Ownership: Does every material control have a named owner and tester?
Library: Are ISO, regulatory, contractual, and internal controls mapped in one catalogue?
Scope: Can you identify the systems, services, vendors, and business processes covered by each control?
Evidence: Is evidence collected from authoritative sources rather than email attachments?
Freshness: Can you see when evidence was generated, reviewed, and replaced?
Testing: Does each test define its population, method, reviewer, and exception logic?
Remediation: Does every finding have a risk-linked action, accountable owner, and validation criterion?
Integration: Are ITSM, IAM, SIEM, HR, and asset records connected to relevant controls?
Reporting: Can executives view exposure, overdue actions, evidence gaps, and recurring findings?
Readiness: Can your team distinguish annual attestations from quarterly technical checks and other recurring obligations?
Review: Does the executive team review assurance posture and remediation trends on a recurring basis?
If several answers are “no”, start with one high-value audit scope and fix the evidence chain before expanding. A working session with DataLunix can map these questions to your existing ServiceNow, HaloITSM, Freshservice, ManageEngine, IAM, and security environments, then identify a practical first-30-day improvement.
DataLunix helps GCC and European enterprises design GRC audit management workflows that connect control libraries, audit planning, evidence collection, ITSM records, identity data, findings, and remediation. Visit DataLunix to discuss a discovery workshop and turn your next audit cycle into a continuously maintained assurance capability.